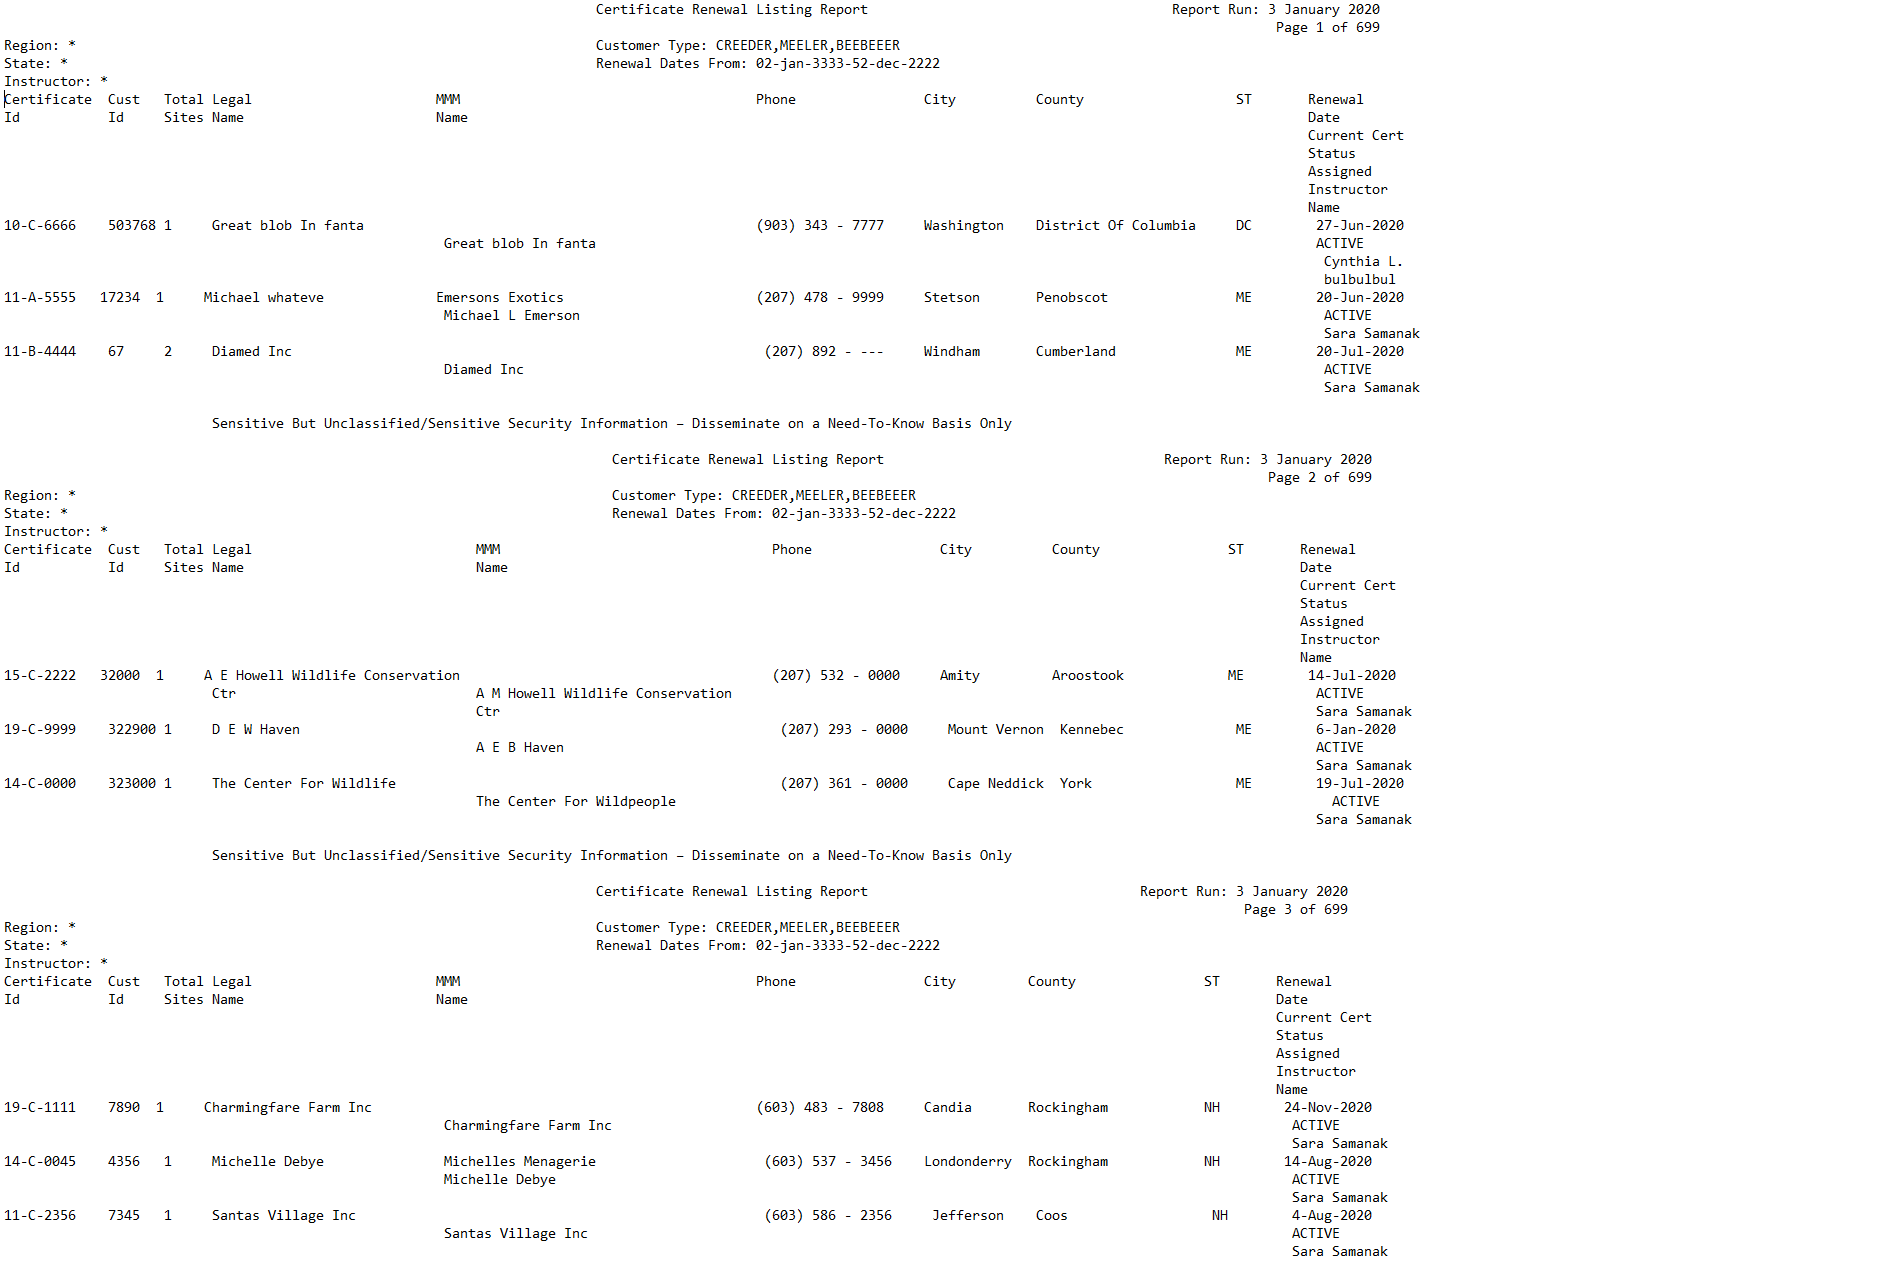
I'm having trouble thinking about the approach on reading a text file. I initially had a PDF file (700 pages worth of table formatted same exact way) which I then converted to a .txt file using the pdftools package.
The text file I end up getting has a bunch of texts (comments) that are not needed and then the table of 8 records and then it repeats itself on and on (see attached file).
Would greatly appreciate any direction on this.
Link to the uploaded file: https://easyupload.io/0lmpbv
1
Are you able to share the text file? It will be very difficult to help out without having access to these data given the very unique structure.
I would read the whole thing into a dataframe using readr::read_csv and tidy it up from there.
If the formatting is irregular, though, it might be easier to read it in using df <- tibble(lines = readLines()) and then use regex and stringr to normalise and split it.
I tried uploading the text file, but am not allowed and a reprex won't help here.
Upload your sample file to a cloud storage service (Like Dropbox, Google Drive, Box, etc) and share a link to it.
Here's a link to uploaded file: https://easyupload.io/0lmpbv
As woodward said you would have to read the data as it is and clean it with regular expressions, see this example (Obviously not a complete solution because honestly, this is going to be a little tedious)
library(tidyverse)

sample_data <- readLines("Sample.txt")

sample_data %>%
    enframe(name = NULL) %>%
    filter(str_detect(value, "^\\d{2}-")) %>%
    separate(value, sep = "\\s+", into = c("cert_id", "cust_id", "sites"))
#> Warning: Expected 3 pieces. Additional pieces discarded in 9 rows [1, 2, 3, 4,
#> 5, 6, 7, 8, 9].
#> # A tibble: 9 x 3
#>   cert_id   cust_id sites
#>   <chr>     <chr>   <chr>
#> 1 10-C-6666 503768  1
#> 2 11-A-5555 17234   1
#> 3 11-B-4444 67      2
#> 4 15-C-2222 32000   1
#> 5 19-C-9999 322900  1
#> 6 14-C-0000 323000  1
#> 7 19-C-1111 7890    1
#> 8 14-C-0045 4356    1
#> 9 11-C-2356 7345    1