How to Remove Duplicate Rows while Retaining a User Specified Column

I have a dataframe like this and want to remove duplicates (in preparation for tsne), but I want to retain my id (not R generated) column so I can later join the dataframe results back to a broader data set for contextual analysis.

id var1 var2 var3......etc. many more vars...
1 1 1 1
2 1 1 1
3 9 5 2
4 9 3 4
5 8 6 2

I'm trying to get this result, removing the id 2 record:
1 1 1 1
3 9 5 2
4 9 3 4
5 8 6 2

Any suggestions on this seemingly simple requirement?

Second question, although I'm using my own generated ids I've yet to figure out what the R dataframe column is called since it shows up as blank in views. Is it possible to call the R row id field using df$rowid? Curious if this is the syntax?

thank you!
dplyr::distinct() may help? This function removes duplicated rows from your dataset, and you can keep your id variable.

The function description is here: https://dplyr.tidyverse.org/reference/distinct.html

Another relevant post I found with Google: https://www.datanovia.com/en/lessons/identify-and-remove-duplicate-data-in-r/

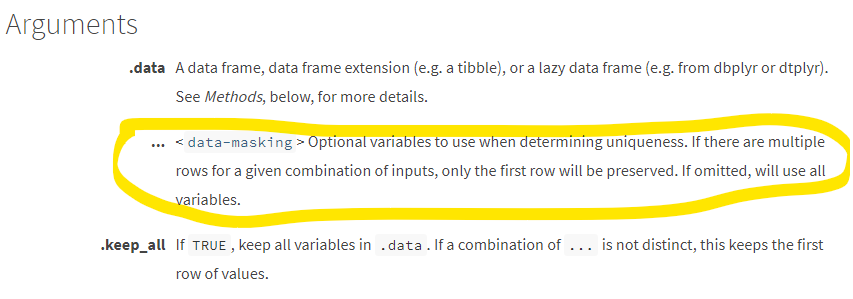
good resources, and I probably just need to dig in some more. I was thinking there might be an expression or argument in unique or distinct which allows the user to specify the any columns to ignore.

I capture a screenshot from the function description:

thanks, I also had my eye on this. Like everything I just need to figure out the syntax, I'm still quite new to R. Appreciate your help!

ok, looks like distinct and unique can't meet my requirements allowing me to easily pick df columns to exclude from unique. However, I was able to solve this by using row.names(df) to get the id's of rows so I could merge data back into the results of the unique function.